

“Every one knew how laborious the usual method is of attaining to arts and sciences; whereas by his contrivance the most ignorant person, at a reasonable charge, and with a little bodily labor, may write books in philosophy, poetry, politics, law, mathematics, and theology, without the least assistance from genius or study…”
What would it mean if anyone may write books…“without the least assistance from genius or study”?
Jonathan Swift first raised this possibility exactly 300 years ago in his great anti-colonial work of speculative fiction, which we call Gulliver’s Travels. Today we are reckoning with the question for real.
Swift invented the large language model. Life imitates art far more than the other way ‘round... The device that allows anyone to write books he calls a word-loom — a much better name than large language model — a kind of giant calculator “made from the strictest computation of the general proportion there is in books between the numbers of particles, nouns, and verbs, and other parts of speech...”
The strictest computation of the proportion there is in books of words .... as good a one sentence description of the functioning of LLMs as any other I’ve seen.
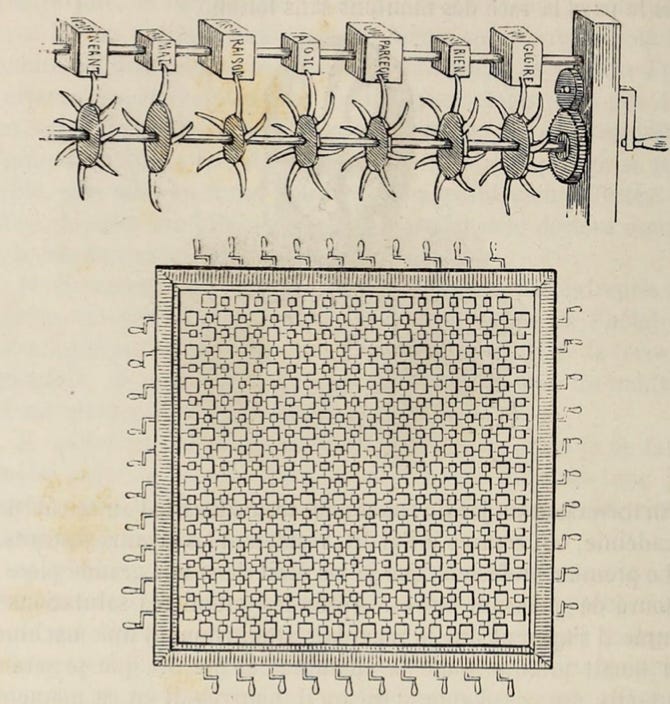
There are other aspects of Swift’s description that are also spot on, including the inventor’s ambitions and need for investment capital:
“...He intended to piece together, and out of those rich materials to give the world a complete body of all arts and sciences; which, however, might be still improved, and much expedited, if the public would raise a fund for making and employing five hundred such frames in Lagado, and oblige the managers to contribute in common their several collections...”
This invention was presented as absurd, along with others brewing in the Grand Academy that Gulliver visited in Lagado — extracting sunbeams from cucumbers, reversing the process of digestion to recover food from excrement, softening marble to make cushions, etc.1 For what is the point of books without authors? Like food reconstituted from shit?
Well, we are finding out. The flood of content is just beginning. I am just back from the excellent Asian Rights Fair in Kuala Lumpur, where an agent offered me English language rights to “Deepseek Rapid Novel Creation Guide”, which “details practical techniques” for mobilizing Deepseek to help you write your novel. The book doesn’t tell you how to prompt Deepseek to write the novel itself of course, that approach might put the Creation Guide author out of business, but among other novel-assisting tasks you will learn to ask Deepseek to “craft emotion and environmental descriptions”. You have probably looked at the excellent Washington Post piece “These 5 charts show how ChatGPT is flooding our lives” , or heard about the tide of AI-generated pirate audiobooks that the AAP is trying to counter by partnering tech firm Vermillio.
Let me focus on the flood as it rushes into my field, scholarly publishing. I made a presentation on this topic to researchers and publishers at the University of Kyoto, and I look forward to more focussed discussions with colleagues in the scholarly publishing world. I think we are in for a crisis. Here are some of the highlights.
There is already plenty of AI-generated text in our research corpus, final version of record as well as preprints. The bibliography of studies looking at this phenomenon is already quite long, even if our methods of detecting AI-generated text are still very shaky (and will always be?) One study found that, by September 2024, 22.5% of computer science abstracts showed evidence of LLM modification.2 A preprint in biorxiv.org by Richard She (2026)3, found that papers published across 13 major journals in 2025 showed a sharp jump to 12.4% containing at least one AI-written passage, versus nearly zero in 2021–2024. The geographic distribution is striking: 32% of papers from South Korean institutions and 26% from Chinese institutions contained AI-generated passages, versus 7.4% from U.S. institutions — and high-selectivity journals had far less AI content than high-volume ones.
Another study, in Science, went a bit further, and looked at the productivity of authors who appear to be using AI tools. It showed that, between January 2022 and July 2024, the number of arXiv preprints published monthly once an author had adopted LLMs in their writing increased by 36.2% relative to nonadopters. The adoption of tools — and corresponding productivity gain — was noticeably higher for scholars with Asian names and affiliations, across arxiv, bioRxiv and Social Science Research Network (SSRN).4
While some hopeful souls argue that having AI generate research articles will advance science, the only empirical findings so far just show that it just means more articles.
My twitter feed is full of offers for things like “Academic Claw” or “AutoResearch Claw” an agent that “runs structured academic research end to end — from question framing to publication-ready synthesis”. A scholar at a highly ranked institution in Singapore published 200 articles in 2025, and I’m told its administration is struggling to respond. I received a proposal the other day from a European humanities scholar who had published eight books of literary studies in 2024 and 2025, five of them with Taylor and Francis, two with Springer and one with Bloomsbury. Very productive!
Academic journal editors that I am talking to report a 30 to 40% increase in submissions so far this year, and expectations that submissions will at least double next year. They privately lament that most of the increase, displaying common signs of AI generation, are coming from Asia.
What’s important to understand here is the relationship of the tools to the incentives for academic publishing. Better to look for explanations of Asia’s take up in the incentive structures, rather than culturalist explanations of some essential AI receptivity (or worse, approach to academic integrity).
The publish or perish mentality is strong everywhere, but even worse in many parts of Asia. I think this is in part because the informal academic cultures that might moderate these trends and nuance the application of KPIs have not had time to mature in the face of the managerial culture of growing universities in quickly developing countries, with the resulting onslaught of performance metrics and mechanical KPIs for research output. This is another reason Japan is a little bit different, as the bigger universities have a longer tradition, and ideas of service and impact are deeply engrained.5
But in developing Asia, As prime ministers ask their ministries of science and/or education to increase R&D, they naturally enough assume a correlation between research publication and research impact, and adopt a KPI of citations and articles published. The ministers’ award research funds to universities based on their ability to contribute to these KPIs. Universities allocate funds, space and headcount to departments and research centres on the basis of their publication records. Jobs are given to researchers based on their ability to enhance these metrics. In Indonesia and Malaysia, students do not get graduate degrees without publishing in recognised journals. When Indonesia first introduced this requirement, in 2012, there were only 300 journals published in Indonesia, and 3000 students coming out of graduate schools in the largest university in the country. Today, there are said to be 10,000 journals published in Indonesia, and research output has skyrocketed. But Indonesia is one of the main victims of the predatory journal industry,6 and quality remains a big question mark. The head of a Malaysian university press told me that to get tenure one must have published 30 Scopus-indexed journal articles. No matter what discipline you work in.
We are reminded of Godhart’s Law: “When a measure becomes a target, it ceases to be a good measure…”
So now that AI breaks the already strained connection between research quality and publication and citation of journal articles, where will we be? One of the most thoughtful commentators on this issue, someone who has done the math to understand the impact of narrow metrics on research output, is Juan Pablo Pardo-Guerra, Associate Professor at UC San Diego, and author of The Quantified Scholar: How research evaluations transformed the British social sciences (Columbia University Press, 2022). A must-read for my sisters and brothers in scholarly publishing and in university administration. See also the delightfully pleasurable new book from C Thi Nguyen, The Score (Penguin, 2026), which looks much more broadly at the problems of using quantified KPIs the wrong way.
In that Kyoto talk referenced earlier, I used this slide to illustrate what I thought the impact of AI would be on a system of misaligned incentives and over-reliance on bibliometrics:
In a recent blogpost, “It’s time to get rid of the peer-reviewed paper”, Pardo-Guerra has looked hard at how AI plays into the publish or perish and research evaluation system. Pardo-Guerra’s assessment:
We have a publishing system optimized for volume, financed by uncompensated labor, controlled by profit-seeking entities, producing increasingly incremental work, now facing an AI-driven capacity to generate competent manuscripts at near-zero marginal cost when the broader research enterprise is under severe fiscal constraint. What exactly is this enormous expenditure of collective intelligence through peer review buying us? What is it safeguarding?
Like a turkey voting for Thanksgiving I find myself agreeing, though for me the issue is more the system of incentives built up on top of journal publishing than publishing itself. As to what happens next, I can’t help agreeing with Pardo-Guerra: an already over-burdened system is likely to visibly fail under AI pressure. The failure will be public. Research publishing will leak legitimacy just at a time when we need our universities and knowledge institutions the most.
In this light, Gen-AI may in fact be giving us an opportunity. The Swiftian absurdity of our situation may in fact inspire us to change, not (just) the technology, but rather the incentive system which is driving its adoption.
In a final irony, the consensus among literary scholars is that Swift’s satire was written against this very system of journal publishing, as it was being born. He was attacking Newton and the scholars of the Royal Society and their new invention the academic journal, every scholar anxious to get out a new piece of writing as soon as possible, to be the one more modern than the next, quality of writing and expression be damned. To cook up the hot take. It only took Swift 300 years to be right.
Swift even foresaw the way I would end this blogpost. I conclude this entry as Swift’s Gresham does in the 1704 Discourse Concerning the Mechanical Operation of the Spirit “in great haste, as the post is just going…”
Absurd indeed, though careful scholars have linked most of them to real papers published by the Royal Society. See Nicolson, M., & Mohler, N. M. (1937). The scientific background of Swift’s Voyage to Laputa . Annals of Science, 2(3), 299–334. https://doi.org/10.1080/00033793700200611. The word-loom is not one however.
Liang, W., Zhang, Y., Wu, Z. et al. “Quantifying large language model usage in scientific papers”, Nature Human Behavior 9, 2599–2609 (2025). https://doi.org/10.1038/s41562-025-02273-8
Richard She, “Fine-Grained Detection of AI-Generated Writing in the Biomedical Literature”, doi: https://doi.org/10.64898/2026.01.01.697311
Keigo Kusumegi et al., Scientific production in the era of large language models. Science 390,1240-1243(2025). DOI:10.1126/science.adw3000
I haven’t studied the matter in detail; this is impressionistic. Also I note that Gulliver visited Japan after his visit to Laputa.
Vít Macháček, Martin Srholec, “Predatory publishing in Scopus: Evidence on cross-country differences”, Quantitative Science Studies 2022; 3 (3): 859–887. https://doi.org/10.1162/qss_a_00213
Maybe AI will be the last straw in the publishing and peer review racket but I doubt it. This game has been going on for a LONG time. It was already obnoxious in 1970.
Publishers might be the gatekeeper because their profit depends on maintaining and protecting copyrights. My courseware is handled by a very small textbook publisher who sent out a STRICT no-AI guideline. I'm happy to obey, since my own guideline is absolute. I want to be proud of a product that bears my name!