

I am still recovering from the exciting schmoozing at the International Publishing Association’s World Congress in KL last week. It was really fun, and the synergy between IPA’s small but powerful team and organizing capacity of Malaysia’s book world was superb. Friends at the Malaysian Publishers Association, and their allies in the Malaysian books ecosystem did a great job. KL was looking great. Among the lesser attractions of the event was chance for Nadim Sadik of Shimmer.ai and I to have an afternoon’s “civilised ding-dong”on the subject of AI and publishing. (That’s his phrase.)
We agreed to speak to the title that was set for us, AI and Publishing: the Good, the Bad and the Ugly.
But rather than look at the AI elephant (or Cthulhu) from three judgemental angles, I decided to use the film as a kind of parable. Here are my remarks, with some bits I dropped restored and definitely some parts improved! Always rewriting...
The Good, the Bad and the Ugly
I’ll take my inspiration more from the characters in the film of this name.
If you remember this was a film made by Sergio Leone, with an iconic score by Ennio Morricone. Like most things in life, it sounds better in the Italian: il buono, il brutto, il cattivo.
What is interesting in the film is how intertwined are the fates of the three main characters. In particular, the Good, Clint Eastwood as Blondie, and the Ugly, Eli Wallach as Tuco, are forced to work together to find a treasure. Each has part of the answer but not the whole. They are deeply suspicious of each other, always double-crossing each other, or threatening to, trying to get away from each other, but in the end realising they have to work together.
And that is my main theme. The good and the ugly need to work together no matter how much they dislike and distrust each other. Because the alternative is to be killed by Lee van Cleef.
A necessary relationship
That ingestion of high quality textual expression is essential to the functioning of large language models should by now be well-established. We should by now understand that the stock phrase “models were trained by reading the internet” hides or at least deflects from the fact that their good performance depends on written expression claimed without permission: books, journalism, academic articles, software, generally copyright protected.
The companies, especially Open AI famously started to hide the sources of the material they had trained on when models got potent. And a recent filing in the consolidated lawsuit against OpenAI has even more shocking accusations about hiding that and other material from the courts — and destroying other evidence.
In fact, discovery in the US trials are throwing up all sorts of fascinating documents. We have the famous memo showing that a certain “MZ” —fully apprised of the risks—approved the use of the pirate database LibGen to train Meta’s Llama model.
Another document that came out of legal discovery in the Bartz v Anthropic case has been less remarked on. It’s a memo that captures Dario Amodei and colleagues strategizing the positioning of the company they had recently founded, Anthropic, and looking ahead at the development of the industry. They wrote this in July 2021... two short months after announcing the launch and first funding round of the company.
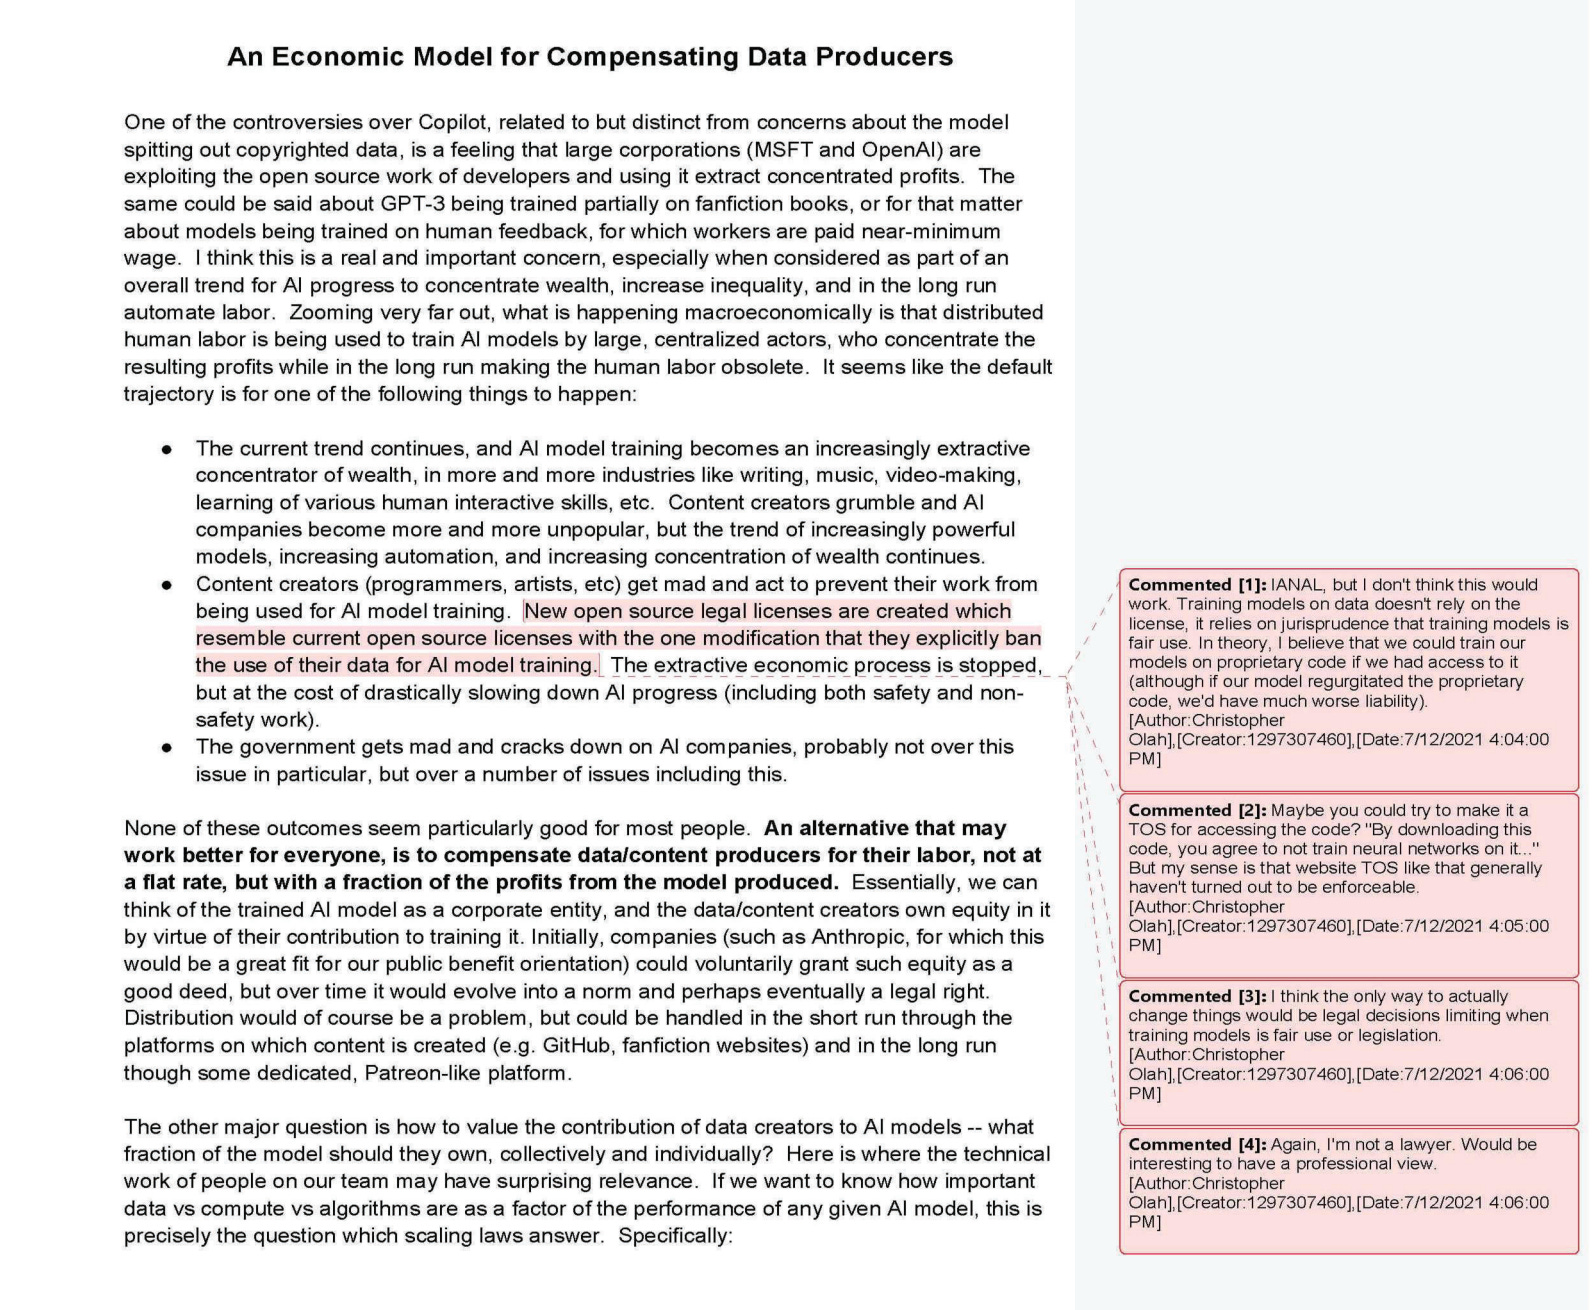
Here is the memo’s capturing of three scenarios for development of the industry, recognising the importance of copyrighted material for the success of generative AI.
The current trend continues, and AI model training becomes an increasingly extractive concentrator of wealth, in more and more industries like writing, music, video-making, learning of various human interactive skills, etc. Content creators grumble and AI companies become more and more unpopular, but the trend of increasingly powerful models, increasing automation, and increasing concentration of wealth continues.
Content creators (programmers, artists, etc) get mad and act to prevent their work from being used for AI model training. New open source legal licenses are created which resemble current open source licenses with the one modification that they explicitly ban the use of their data for AI model training. The extractive economic process is stopped, but at the cost of drastically slowing down AI progress (including both safety and non-safety work).
The government gets mad and cracks down on AI companies, probably not over this issue in particular, but over a number of issues including this.
None of these outcomes seem particularly good for most people. An alternative that may work better for everyone, is to compensate data/content producers for their labor, not at a flat rate, but with a fraction of the profits from the model produced. Essentially, we can think of the trained AI model as a corporate entity, and the data/content creators own equity in it by virtue of their contribution to training it.
Why was this path not pursued? Well, you can see the reason right in comments in the Word doc. One of Dario’s co-founders, Chris Olah, not a lawyer, says forget about it, our whole industry is built on the idea that training models on copyrighted content is fair use, and so you can’t introduce this kind of scheme without blowing up that assumption...
They knew precisely what they were doing, and they predicted how copyright holders would react. Well, …duh… What they didn’t predict exactly is that scenarios one and two could both happen at the same time: content creators got mad, but were not able to stop “the current trend”. I was only a year and a bit behind them in seeing similar scenarios, and wondering how it would play out - starting this Substack as a place to track the action…
What the software engineers taught me
Two weeks ago I signed up to attend a session organized by AI Singapore, a national organization that’s aimed at growing the local AI ecosystem, and driving AI adoption. It was with some trepidation that I stepped into the space, meeting all the techies, including the young people from AI Singapore, with their branded windbreakers (that Singapore aircon you see...).
I was blown away by what I heard. The number one concern addressed in the session and expressed by participants was the fear of too much cognitive offloading. One speaker cited an AI Singapore survey that showed that 62% of software engineers were concerned about their own de-skilling... about their own skills eroding with use of AI coding agents. And the concern was higher the heavier the use.
What is cognitive offloading? It’s a well-developed concept for what happens when we delegate part of our cognitive processing to services, technologies, even other people. Think of your wayfinding skills and Google Maps. It is not even necessarily a bad thing, if it frees up cognitive resources for more important tasks, and the loss of skills does not mean a loss of resilience. But with AI the risks of offloading seem particularly high. A recent important paper from the Wharton School talked about “cognitive surrender” to AI. Thinking—Fast, Slow, and Artificial: How AI is Reshaping Human Reasoning and the Rise of Cognitive Surrender
What are the habits of mind that evolve when you have the power of LLMs at your finger tips? Convenience they say is the most addictive drug of all, and what if your access to knowledge, to thinking and reasoning, your ability to write, can be performed “without the least assistance from genius or study”, as Jonathan Swift put it.
The approach taken in the AI Singapore seminar was mostly about building habits of mind to resist the wrong sort of offloading. (Not all — @thekush was a speaker and made the excellent point that it’s a matter of inventives and AI tool design — existing designs encourage the wrong kind of offloading in favor of engagement.) That approach, the focus on individual “tool use” puts all the burden on us as individuals to just use the models better. Be careful with that chainsaw! It will be our fault if we are de-skilled, or lose a finger.
But it is not just up to us as individuals to solve the problem, though of course we should try. Just consider the AI as a tool! Yes, but it is a tool that changes our very relationship to knowledge. It is a medium, it is a system. The forms and affordances of the media we use shape our minds, and our social relations, in ways we may not always recognise or understanding. Powerful AI chatbots are a kind of cognitive heroin, and I (have reason to) doubt our ability to resist their addictive power.
So my question — If individuals are experiencing cognitive surrender, what does that mean at scale? And what does it mean that if at the same time, our collective institutions or systems for creating and sharing knowledge are being undermined?
Let me spend a minute on that part of the equation, to make two points.
It has been clear for some time that LLM-powered chatbots are disintermediating writers and publishers.
The traffic sent to online publishers by Google has plummeted with the introduction of AI Overviews, which now reach 2 billion users. And why not? If you are going to Google just to answer a simple question, do you really need to go to a website?
A peer-reviewed survey of Pakistani medical students found 94% used AI chatbots, 51% daily, with ~12% showing high emotional-psychological dependence.
June 2026 Pew Research shows half of Americans have used chatbots, and around half of those, or a quarter of all Americans, use chatbots daily.
In Feb 2026 the UK reported that 94% of undergraduates had used AI in some capacity for their class assignments.
15% of American adult users use chatbots for emotional support and advice, and for companionship. That’s Pew also.
one detailed panel study of adolescents found those with weaker executive functioning perceived generative AI as more useful — the less developed their decision-making skills and goal-oriented behaviour, the more likely they are to delegate to AI. This kind of self-selection is likely to spiral...
For work-related research, to do homework, for companionship, for amusement, to get medical advice, to do research, to find a recipe, to fill the yawning hole in your life, the AI is there. And at least some of that presence is working to demonetise us (in the phrase of Melissa Fleming, UN Undersecretary for Communication, in her remarks to the Congress).
Secondly, our existing systems are starting to drown in AI output.
We are already seeing a 30 to 40% increase in academic journal submissions. Academics who use AI in their writing (as tracked in the use of certain language patterns) have proven to be 40% more productive than their colleagues, in a study that tracked submissions to pre-print servers.1
Such superabundance (as Nadim calls it), has been a fact of life in some areas of publishing for some time, but in academic publishing the addition of GenAI to the mix is threatening to break a system already under severe pressure.
The sum of all three effects - and others! - epistemic risk
So if individuals are experiencing cognitive offloading, beginning to surrender their cognition, and if our existing systems are being put under huge pressure in different ways, how does that all add up?
A recent paper uses the very handy concept of epistemic risk. This was a paper that comes from a large group of researchers, led by Mick Yang at the University of Pennsylvania, Kellin Pelrine at FAR.AI and which includes famous AI researcher Yoshua Benguio. My factors are not the only ones it covers…
What is epistemic risk?
“threats to humanity’s collective capacity to know things accurately, reason well, form beliefs, and maintain a healthy information environment.”
Now what’s interesting that this is coming from the AI research community. The safety side of the community to be sure. This morning we heard about Malaysia’s placement of literacy as an essential building block to an AI-ready knowledge infrastructure. One of the reasons this makes such good sense is that real literacy is a potential counter to the epistemic risk posed by AI.
We’re talking about risks — not predictions! But given the results of our recent two decade society-wide experiment with social media, I think we need to take risk mitigations in our information ecosystem much more seriously.
If we offload too much cognitive work to AI, and if we destroy the systems we have and the incentives we need to create, test, disseminate new knowledge, then we risk what Nobel-prize-winning economist Daron Acemoglu calls knowledge collapse. See his AI, Human Cognition and Knowledge Collapse.
Knowledge collapse is what happens when AI systems solve our individual problems, but we stop investing in systems of shared knowledge. Acemoglu’s paper is detailed math-based economics of a kind I never really resonated with, but in this case I am willing to offload to him and his colleagues the cognitive work of understanding how we might mathematically model flows of information in an AI agentic world. Their argument is that existing systems of knowledge creation involve a weak signal to public knowledge accumulation, and that the loss or lessening of the strength of this signal in AI agentic deployment could eventually lead to the collapse of public knowledge.
Mitigation
How can we ensure that signal is strong enough, even if its circuits change? The first step is to preserve the incentives for new creation that enters the public sphere. This likely means we need a world where content is licensed in AI contexts.
But preserving those incentives are only part of the equation. It will help enormously if AI systems are grounded, not necessarily in some single authority’s delineation of “the facts”, but in attribution, and systems of correction and certification. LLMs may always hallucinate to some degree, but the epistemic risks of highly persuasive and authoritative-sounding models will be minimised if they are anchored in systems that preserve responsibility for speech, for claims. Remember that publishers put our addresses on the copyright page of books — why? so you know where to go to correct something, where to sue us if we cross a line, or as we heard yesterday to heart-breaking effect, in some countries, where to arrest us.
It is certainly seems possible to adapt the truth systems of publishing for an AI world. We should be able to build AI systems that include robust citations, and traceability, at least if we treat the external content as the source of truth claims, and not the probabilities that emerge from the complex vector space inside an LLM, interesting as they may be. It should be possible to make sure that we have ways of ensuring that corrections make their way into the knowledge ecosystem. It will require licensing for RAG and other systems of grounding content.
In short, both parties are needed to find the treasure. It will require the good and the ugly to work together.
Ah, so who exactly is the Good and who is the Ugly?
I have some idea of who is the Bad in this parable. I’ll reserve that label for those who actively seek to destroy systems of truth-finding and shared public knowledge in the interests of exerting raw power (or sacrificing them on an altar of some misconceived notion of transcendence). Lee van Cleef looks a bit like Vladimir Putin, no? Or is it Elon Musk?
Of course we would like to see ourselves as the good, Clint Eastwood wearing that very stylish poncho. But I think the real message of Sergio Leone’s film is that the Good and the Bad are cartoon characters — creations of cinema, exaggerations of our imagination. I suspect that most of us are in fact “the ugly”: the Eli Wallach character, making do, embedded in social circumstance, the product of very particular paths, clever for sure, but with limits to our knowledge and abilities, forced to make compromises.
But if we are canny, determined and stay closer to the Good than the Bad, we will share the treasure in the end.
Keigo Kusumegi et al., “Scientific production in the era of large language models”, Science 390,1240-1243(2025). DOI:10.1126/science.adw3000